Skip to content

We use cookies for a better experience. Enable ads to help keep Toonade free.

Privacy
Toonade

GPT Token Counting

Token Calculator

Count tokens for any text with o200k_base, the tokenizer behind GPT-4o, GPT-4.1 and GPT-5. Get exact token counts, size information, and cost estimates.

Input Text

Paste or type text to calculate tokens

Token Analysis

Detailed token and size information

Enter text to see token analysis

How the token calculator works

Large language models don't read words or characters, they read tokens: chunks of text that can be a whole word, part of a word, a number or a punctuation mark. Toonade counts tokens with o200k_base, the tokenizer OpenAI uses for GPT-4o, GPT-4.1, GPT-5 and the o-series models. Everything runs in your browser, so your text is never uploaded.

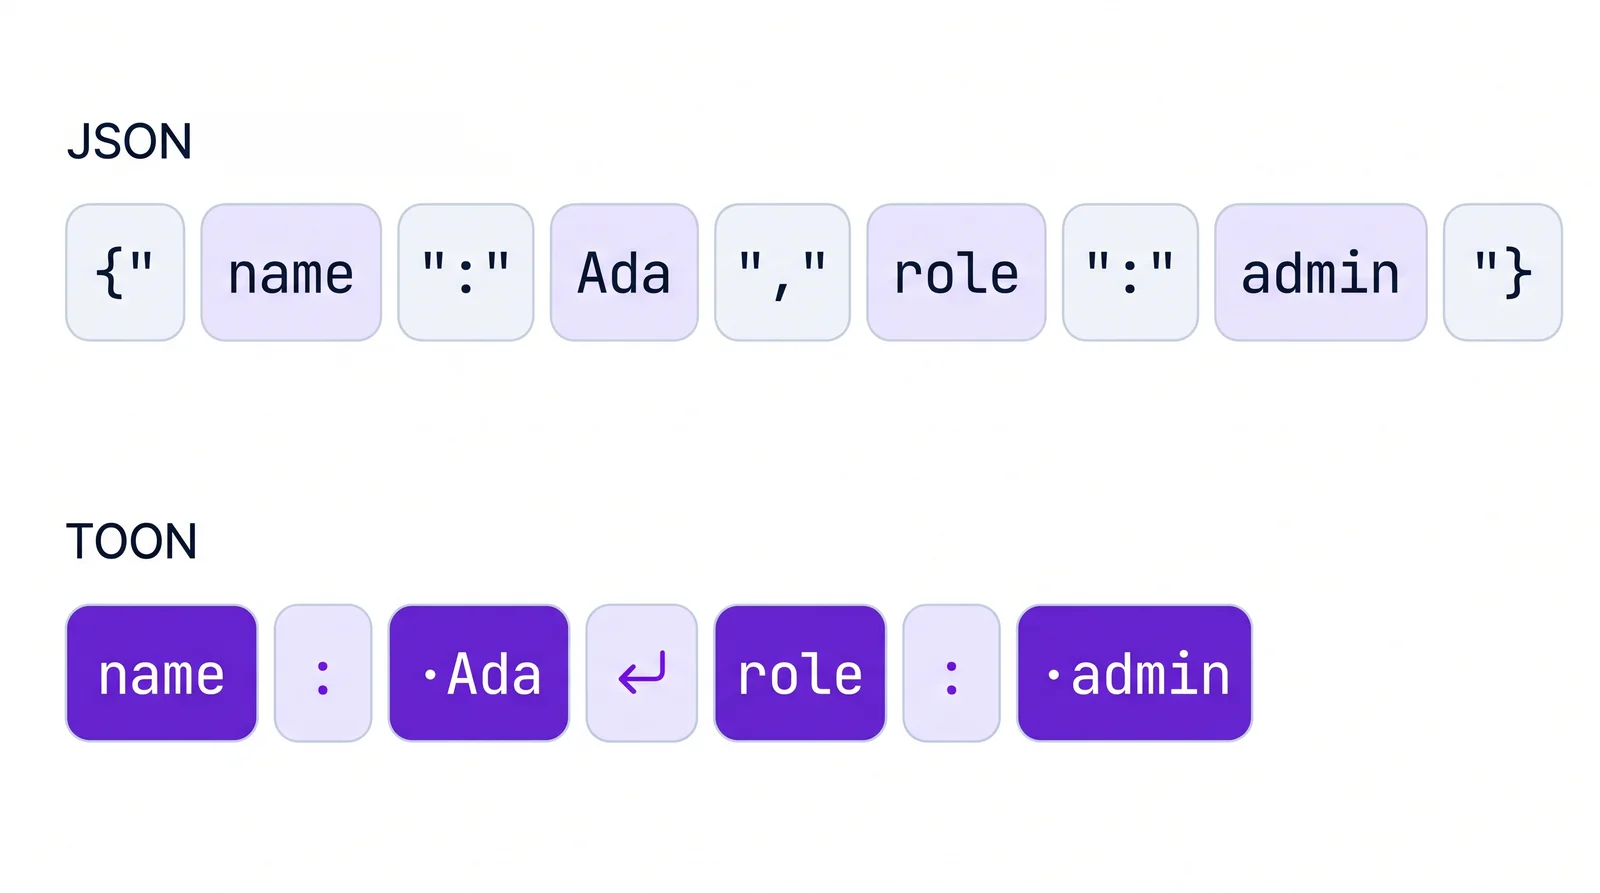
How a tokenizer splits the same record. As JSON, name Ada and role admin take 9 tokens, because quotes, braces, colons and commas count as separate tokens. As TOON, written name: Ada and role: admin on two lines, they take 7 tokens.
Each chip is one token: 9 for the record as JSON, 7 as TOON. Punctuation costs tokens too, and TOON uses less of it.

Tokens vs. words vs. characters

As a rule of thumb, one token is about four characters of English text, or roughly three quarters of a word, so 100 tokens is around 75 words. Code, JSON, numbers and most non-English languages use more tokens per word, which is why an exact count beats an estimate.

Why token counts matter

API pricing, context windows and rate limits are all measured in tokens. Checking a prompt's token count helps you stay within a model's context window, estimate cost before sending a request, and spot prompts that are bigger than they need to be.

Use fewer tokens for structured data

If your prompt includes JSON, converting it to TOON (Token-Oriented Object Notation) often cuts the token count noticeably, especially for arrays of objects that share the same fields. Try the JSON to TOON converter and compare the counts here, or read TOON vs JSON for the details.

Frequently asked questions

Is this token counter accurate for ChatGPT and GPT-4o?
Yes for plain text: it uses o200k_base, the same encoding as GPT-4o, GPT-4.1, GPT-5 and the o-series. Chat requests add a few formatting tokens per message, and older models such as GPT-3.5 Turbo and GPT-4 use cl100k_base, so their counts can differ slightly.
How many words is 1,000 tokens?
Roughly 750 English words. The ratio depends on the language and the content: code, data and non-English text usually need more tokens per word.
Can I count the tokens in a file?
Yes. Use the upload button to load a .txt, .json or .toon file and the calculator shows its token count, character count and UTF-8 size.
Does it work for Claude, Gemini or Llama?
Those models use their own tokenizers, so their exact counts differ. For them, treat the result as an estimate.
Is my text sent to a server?
No. Tokenization runs entirely in your browser and your text never leaves your device.